An analytics philosophy
I think about analytics as sitting in the middle of the feedback loop.
You make a plan, put it in market, see what happened, figure out what it means, decide what to do next, and then do it again.
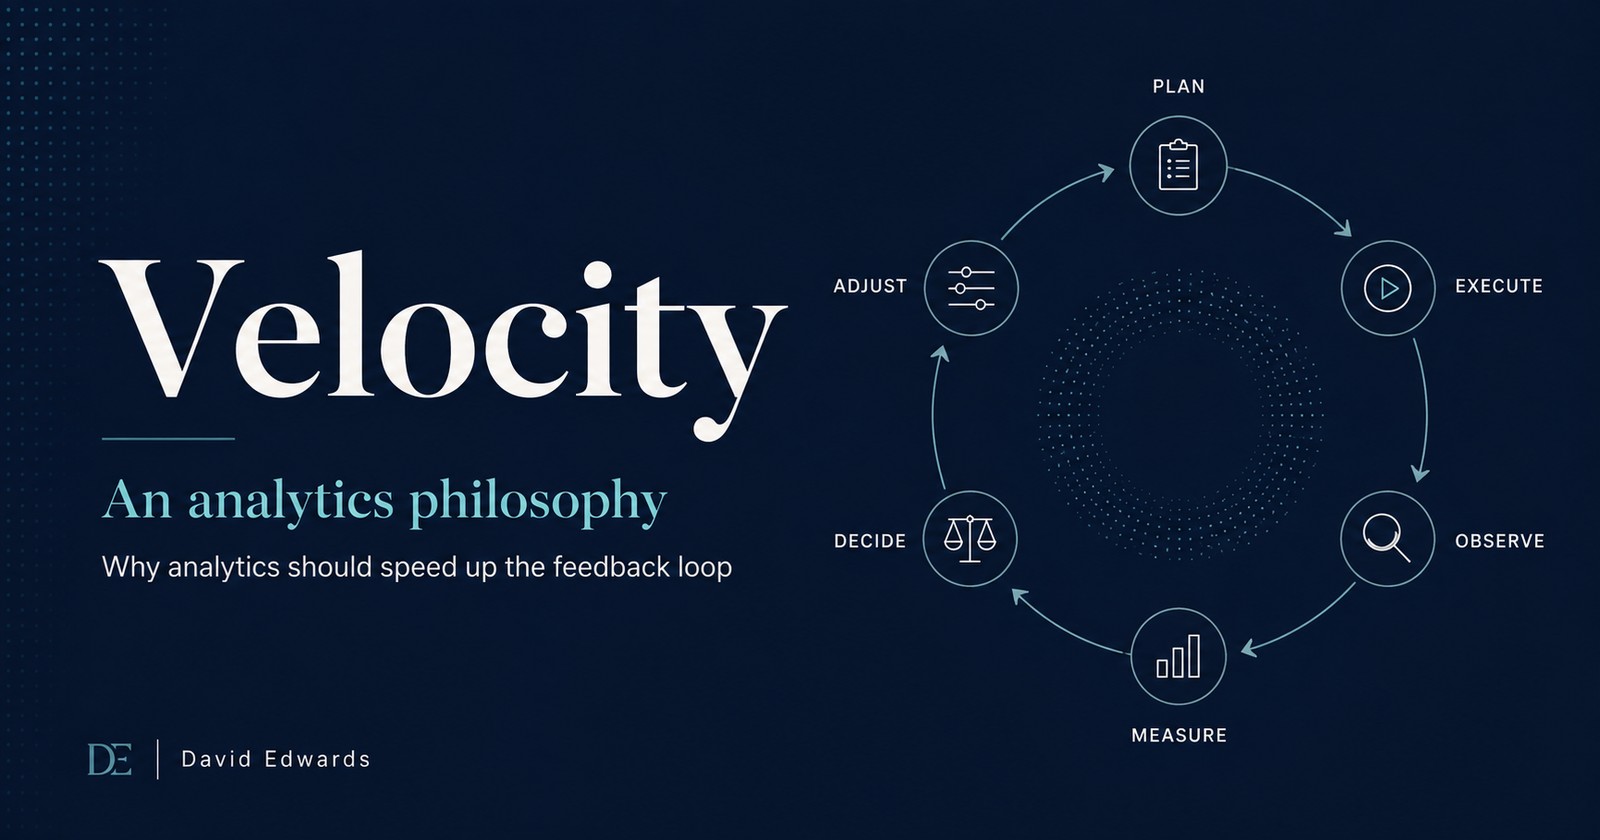
We sit right in the middle of that. So yes, getting the answer right matters. But if it takes three months to get there and there’s nothing left to change, I’m not sure how useful that answer actually was.
I’ve spent a lot of years watching good analysis land too late to change anything. At some point that stopped feeling like bad luck and started feeling like a design problem.
That’s what I mean by velocity: how quickly a team can learn something, do something with it, and start the next loop.
Why speed matters
The obvious answer is that faster decisions are useful. I think the bigger thing is that the learning stacks.
Say one team gets through a meaningful learning cycle every six weeks and another one does it twice a year. The first team hasn’t just learned more things by the end of the year. The questions they’re asking in June are informed by things they learned in March.
The slower team is still waiting on March.
Then the same thing happens again. Every answer changes what becomes worth testing next, so the distance between the two teams keeps getting bigger.
We spend a lot of time arguing about whether one method is better than another in isolation. That matters. But I think we underweight the value of simply getting through more good learning cycles.
A slightly better answer three months from now isn’t necessarily worth more than a good-enough answer while you can still do something with it.
The two levers
Analytics has two broad ways to make the loop move faster: technology and measurement.
Technology is mostly about how long it takes to know what happened.
That’s pipelines, cleaning, tagging, automation, AI. Basically all the stuff between data existing somewhere and somebody being able to actually use it.
Measurement is about how confident we can be in what happened and why.
Stats, models, test design, causal inference. It’s the difference between seeing a number move and having enough evidence to believe something caused it.
Most of what we do comes back to one of those two things: make the information available faster, or make it trustworthy enough to use.
The problem is that sitting in the middle cuts both ways.
Analytics can speed that process up dramatically. We can also be the bottleneck.
We can always ask for another cut, another control, another two weeks of observation. Sometimes that’s absolutely the right call. Sometimes we’re just making the answer more defensible without making the decision any better.
There’s a point where more rigor changes what you should do, and there’s a point where it mostly changes how comfortable the analyst feels presenting the result.
We have to get better at knowing which one we’re doing.
Measurement can’t be the last slide
The failure mode I run into all the time is somebody asking near the end of a planning conversation, “Okay, so how are we measuring this?”
By then the budget’s allocated. Audiences are locked. Creative is built.
And most of the important measurement decisions have quietly already been made for you.
Maybe the markets weren’t set up in a way that lets you test anything. Maybe there’s no holdout. Maybe the creative wasn’t tagged properly. Maybe the campaign structure makes it impossible to separate the thing somebody suddenly wants an answer about.
Whatever you design at that point can probably grade the plan.
It’s much harder for it to inform the plan.
Take a pretty basic example.
Two teams run essentially the same campaign.
The first team builds beautiful reporting. Three weeks after the flight ends, the readout is clear: short-form creator content beat the polished product demos.
That’s genuinely useful to know.
The budget is also entirely spent.
The second team started with the question. They knew they wanted to understand whether creator content performed differently, so they built that into the campaign. Creative was tagged correctly. Spend was distributed across the hypotheses on purpose instead of by accident. The results were readable while the campaign was still running.
Halfway through, they had enough signal to move more of the remaining budget toward creator content.
The analysis doesn’t even have to be better.
One team still had money left to move.
That’s the difference I care about.
What are we actually going to do with this?
This is probably the question I come back to most when we’re designing measurement.
What are we actually going to do with the answer?
Not “what KPI are we measuring?” Not “what study can we run?”
What decision changes?
Say we run a study and the result is positive. Great. What happens next?
Do we move budget? Change the creative? Change the audience? Stop doing something? Scale something?
What happens if it’s negative?
What happens if it’s inconclusive?
If none of those answers would actually change the plan, I start questioning what we’re buying with the measurement in the first place.
That doesn’t mean the work is useless. Sometimes you really are trying to establish a baseline or understand brand health. That’s fine.
But that’s different from pretending the study is there to drive an optimization decision.
The same problem happens when the method doesn’t match the question.
If the actual business question is incremental sales and the only thing you’re running is a brand lift study, you can execute that study perfectly and still not answer what the team actually needed to know.
That’s why I want the decision first and the method second.
If there is no plausible result that changes what you do, you’re not measuring for a decision.
You’re documenting.
Bias toward action, not certainty
The purpose of measurement isn’t to eliminate uncertainty.
It’s to get uncertainty low enough to act.
That distinction matters because I think analytics teams naturally gravitate toward “do we know the true answer?”
Of course we want to know the answer.
But in practice I care more about: do we know enough to make a better decision than we would’ve made without this?
You can usually answer that question much earlier.
It also helps to remember you’re not getting one shot at this. We can take a read now and move, then keep learning. Maybe a platform read points one direction, an incrementality test gives us a better answer a month later, and MMM eventually gives us another view at the mix level. Sometimes they agree. Sometimes they don’t. That’s useful too.
Tests can help calibrate the models over time. If a geo test says one thing and the model says another, I want to understand why. Maybe the test changes what we believe. Maybe it exposes something the model is missing. The point is that each read gives the next one more information to work with.
So acting on an early read isn’t the same as betting everything on it. It’s the first pass. Later work can reinforce it or tell us we were wrong. Either way, we’ve learned something sooner than the team still waiting for the perfect answer.
That’s why I like setting decision rules up front.
If we see X, what are we going to do?
If we see Y?
What if the answer is basically noise?
Have that conversation while you’re designing the test, not after you’re staring at a number you have feelings about.
It forces everybody to admit what would actually change their mind before they know which answer they’re going to get.
And I’m not arguing that every decision should ride on a directional read after three days.
Moving $50K between two creative approaches and setting next year’s $50M channel mix are not the same decision.
The cost of being wrong is different, so the amount of certainty you should demand should be different too.
More rigor is valuable when more rigor can change the decision.
Past that point, sometimes we’re just slowing ourselves down.
This also isn’t an argument for running more tests. Testing everything fragments your budget and your signal, and then nothing reads cleanly. It’s part of why I want a learning agenda in the first place — so we’re covering the questions that actually matter instead of answering whatever came up last week.
The tell
I’ve started noticing this in planning meetings.
You can usually tell how serious a team is about learning by when measurement comes up.
If the buy is basically finished before somebody asks how we’re going to measure it, most of the damage is already done.
If the measurement questions are being asked while the plan is still being shaped, now you have a chance to build something that actually teaches you something — while there’s still time to use the answer.
That’s the philosophy.
The rest of this site is mostly about how to build it.